
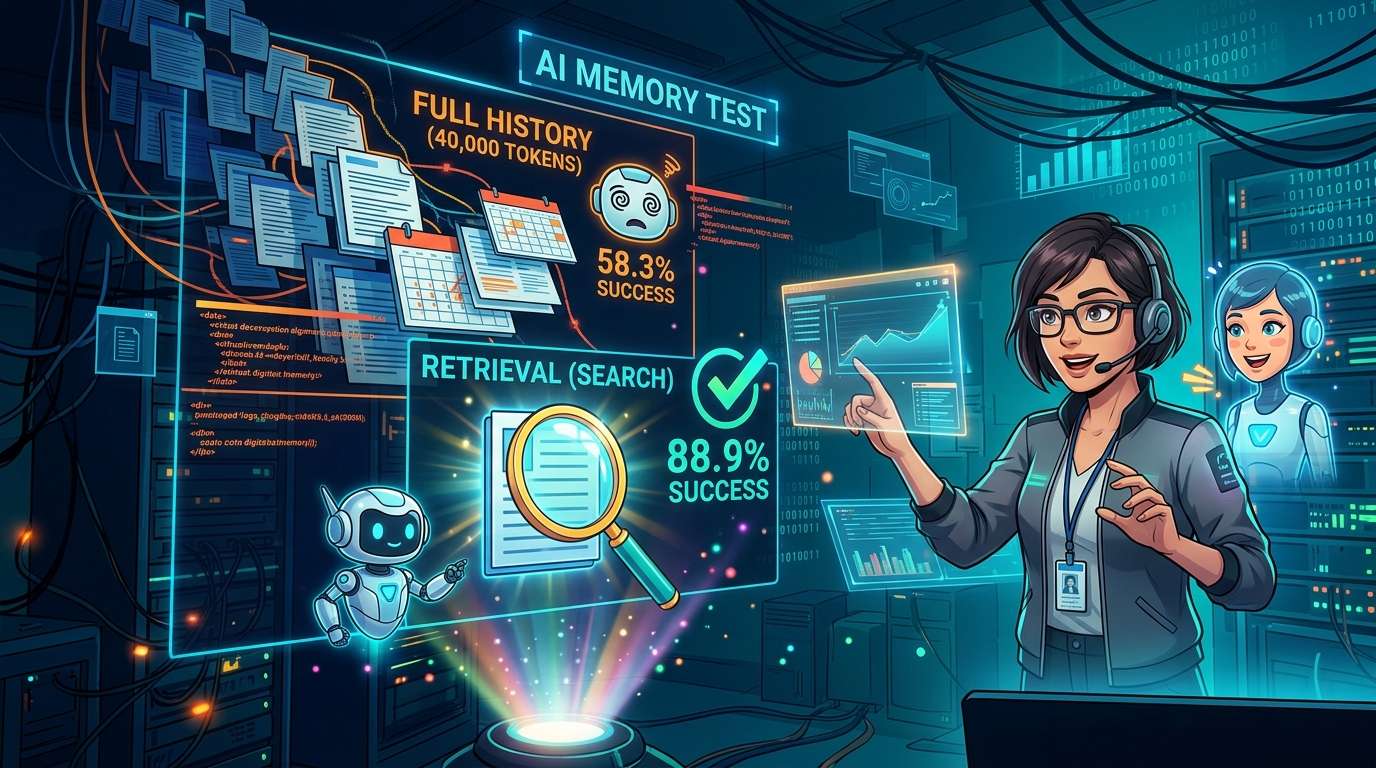
A test comparing four ways to give AI assistants “memory” has been published by data science outlet Towards Data Science. In a trial using about 40,000 tokens of conversation history for a fictional project manager and 30 requests, GPT-4o mini’s task success rate was 58.3% when given the entire history, compared with 88.9% when given only relevant details retrieved from it.
“Remembering” and “being able to use it” are two different things
The test was inspired by DolphinBench, a new benchmark for measuring AI memory performance. The full text is available inthis evaluation article.
Many traditional memory tests directly ask about past facts, such as “What is Sam’s favorite coffee shop?” But the creators of DolphinBench say the question itself can hint that the answer is recorded somewhere. Instead, the test gives the AI a task, such as “Order coffee,” and checks whether it uses the correct information.
The benchmark is designed around three fictional people, each with about 500,000 tokens of conversation history and 200 requests. Results are required to report not only accuracy but also cost and time.
The test was created by a company that sells a memory system called Mem0. In its announcement, the company said its setup led the field, completing 70.67% of requests successfully. The author of this evaluation did not reproduce DolphinBench or test any particular company’s product. Instead, they borrowed the idea and built a small experiment of their own.
Four memory methods tested with Dana, a fictional project manager
The experiment centered on Dana Whitfield, a fictional project manager. The author prepared a year’s worth of conversation history, comprising 80 exchanges, and planted details throughout it.
A year of history and 30 requests
The history totals about 40,000 tokens. Thirty exchanges each state one fact, such as a regular lunch spot, a meeting time, a project launch date or who is responsible for something. Eleven later exchanges change those facts, while the remaining 39 are small talk about things like printers, trains and the weather. Everyday conversation was deliberately mixed in so the facts would not stand out.
There were 30 requests. Each called for using a tool to schedule a meeting, order a meal, send a message or assign a task; nine required two facts, such as a person responsible and a date. Scoring ignored the wording of the response and looked only at whether the values passed to the tools were correct. The author also included one straightforward question about each fact to see whether the model could provide the latest value.
The four methods compared
There were four methods: “No memory,” which provided no history; “Full history,” which supplied all 40,000 tokens every time; “Summary,” which read the history in stages and repeatedly rewrote a summary of about 1,000 words; and “Retrieval,” which supplied the five history excerpts most relevant to each request.
The difference is like handing over an entire year’s diary every morning, giving someone a one-page cheat sheet they have compiled, or pulling out only the relevant pages for each request.
The models were OpenAI’s GPT-4o mini and Anthropic’s Claude Haiku 4.5, with 1,260 runs in total. Records of all the experiments are available in the experiment-tracking tool Weights & Biases.
Comments