
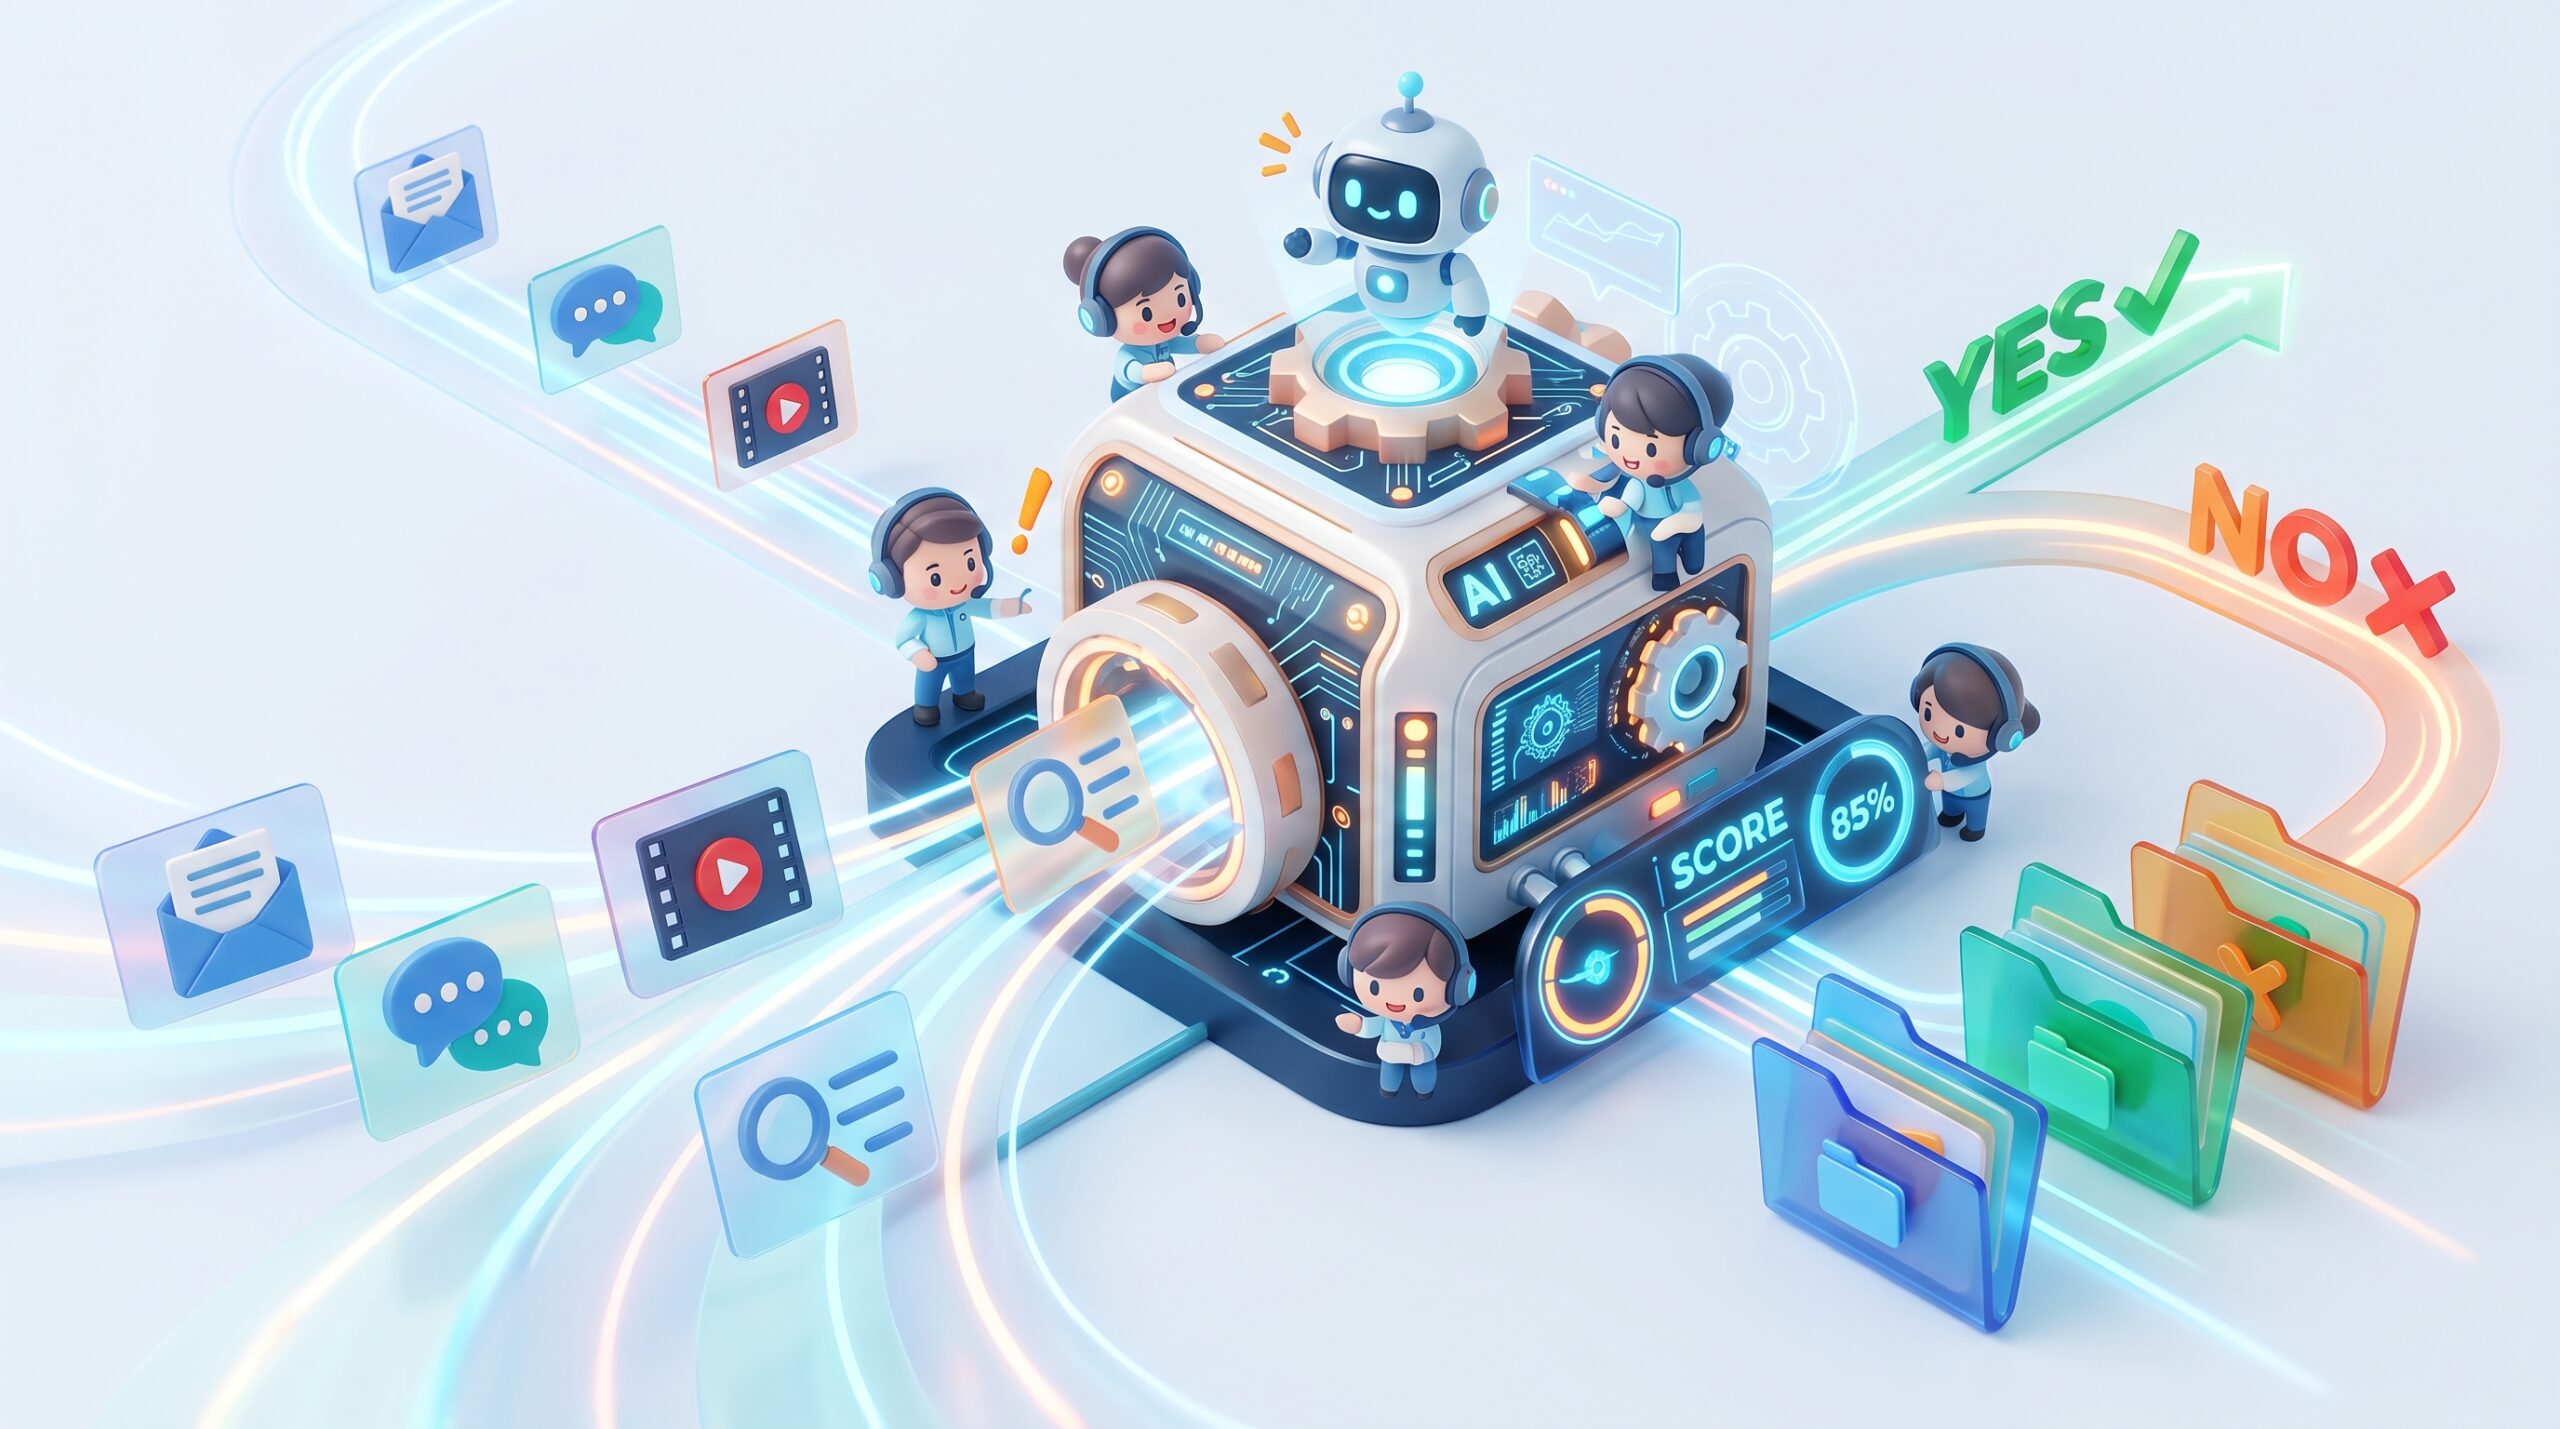
TypeSafe’s Jev is an AI designed to add judgments, classifications, and scoring of text to applications. Here’s an overview of Jev.
Jev Is an Application’s Decision-Maker, Not a Conversation Partner
The quickest way to understand Jev is to consider what you want an AI to return. Rather than “Explain this text,” think “Is this text an advertisement?”, “Is this work-related or personal?”, or “How relevant is it as a search result?” Jev handles questions like these, where the format of the answer can be determined in advance.
Conversational AI is best known for answering questions in prose. Jev, by contrast, is intended for developers to use inside software. Rather than having users talk directly to Jev, it is positioned to handle tasks such as sorting information and directing processes behind the scenes in the apps they already use.
The point of connection is an API. An API is an interface that lets an app request processing from another service and receive the result. You send text and a question to Jev, get back a judgment, and use it to determine the app’s next action.
It Returns Judgments, Choices, or Scores
The materials describe three main use cases: making judgments, such as whether something is an advertisement; choosing from options, such as a destination folder; and assigning scores, such as relevance ratings for search results. These AIs are presented as “judgment models,” meaning models that make decisions.
For example, an email-organizing app could take the message body and select a category from options such as “Work,” “Personal,” and “Other.” This is an example to explain the concept: instead of reading a lengthy explanation and extracting the category, the app receives directly the answer it can use.
Standard large language models can also classify text and produce output in a set format. The difference is not whether they can classify, but that Jev is designed and offered primarily for such judgments. However, the materials provided do not establish Jev’s internal structure or how its performance compares with general-purpose language models.
Reducing Small Frictions in Search and Video Watching
Examples of development projects include a browser extension that skips sponsored segments in YouTube videos, a feature that removes negative comments from chats, Gmail search aligned with the user’s intent, and task filtering. The materials also describe attempts to change how users copy and paste, drag and drop, and search within a page.
What these examples have in common is that they select information that already exists rather than create new text. Keep the parts you want to see, find the email you’re looking for, or narrow down the items that need attention. One way to view this is that AI is moving from chat interfaces into everyday interactions.
However, the development examples presented are not the same as reliable product features. For example, when removing “negative comments,” the outcome depends on how harassment is distinguished from legitimate criticism. Before adopting such a feature, it is necessary to define what should be excluded and check its results, including cases where content was removed by mistake.
AI’s Job Is Not Just Generating Text
Materials dated October 10, 2026, describe several companies offering judgment models in formats similar to Jev. These return answers that software can readily use, such as the probability that a condition is met, a selection from a set of options, or ratings at different stages.
The underlying point is that AI does not need lengthy text at every stage when carrying out multiple tasks. For decision points—such as which process to use next or whether a result meets a condition—processing can continue with a choice or a judgment value.
Jev’s approach is to place decision-making functionality inside an app rather than treat AI as a conversation partner. However, a simple answer format does not necessarily mean the decision itself is simple. The same materials also note in an early assessment that challenges remain around the consistency of judgment models and complex decision-making.
When Adopting It, Define the Boundaries of Its Decisions Before Focusing on Speed
For practical use, it makes sense to first consider separately what you want the system to judge and what happens if it gets something wrong. The impact of a misjudgment differs between labeling an email and automatically hiding a comment. Designing a way to send uncertain cases to a person is also worth considering.
Returning a short answer does not necessarily reduce the cost of the overall system. The materials also point out that integrating Jev to compress the conversation history of a coding assistant AI could undermine mechanisms that reuse past inputs to keep costs down.
The materials provided do not include Jev’s specific pricing, independent accuracy testing, or terms for data storage and use. For deployments involving work emails or customer comments, these conditions and the rate of misjudgments on actual inputs should be checked separately.

Comments