
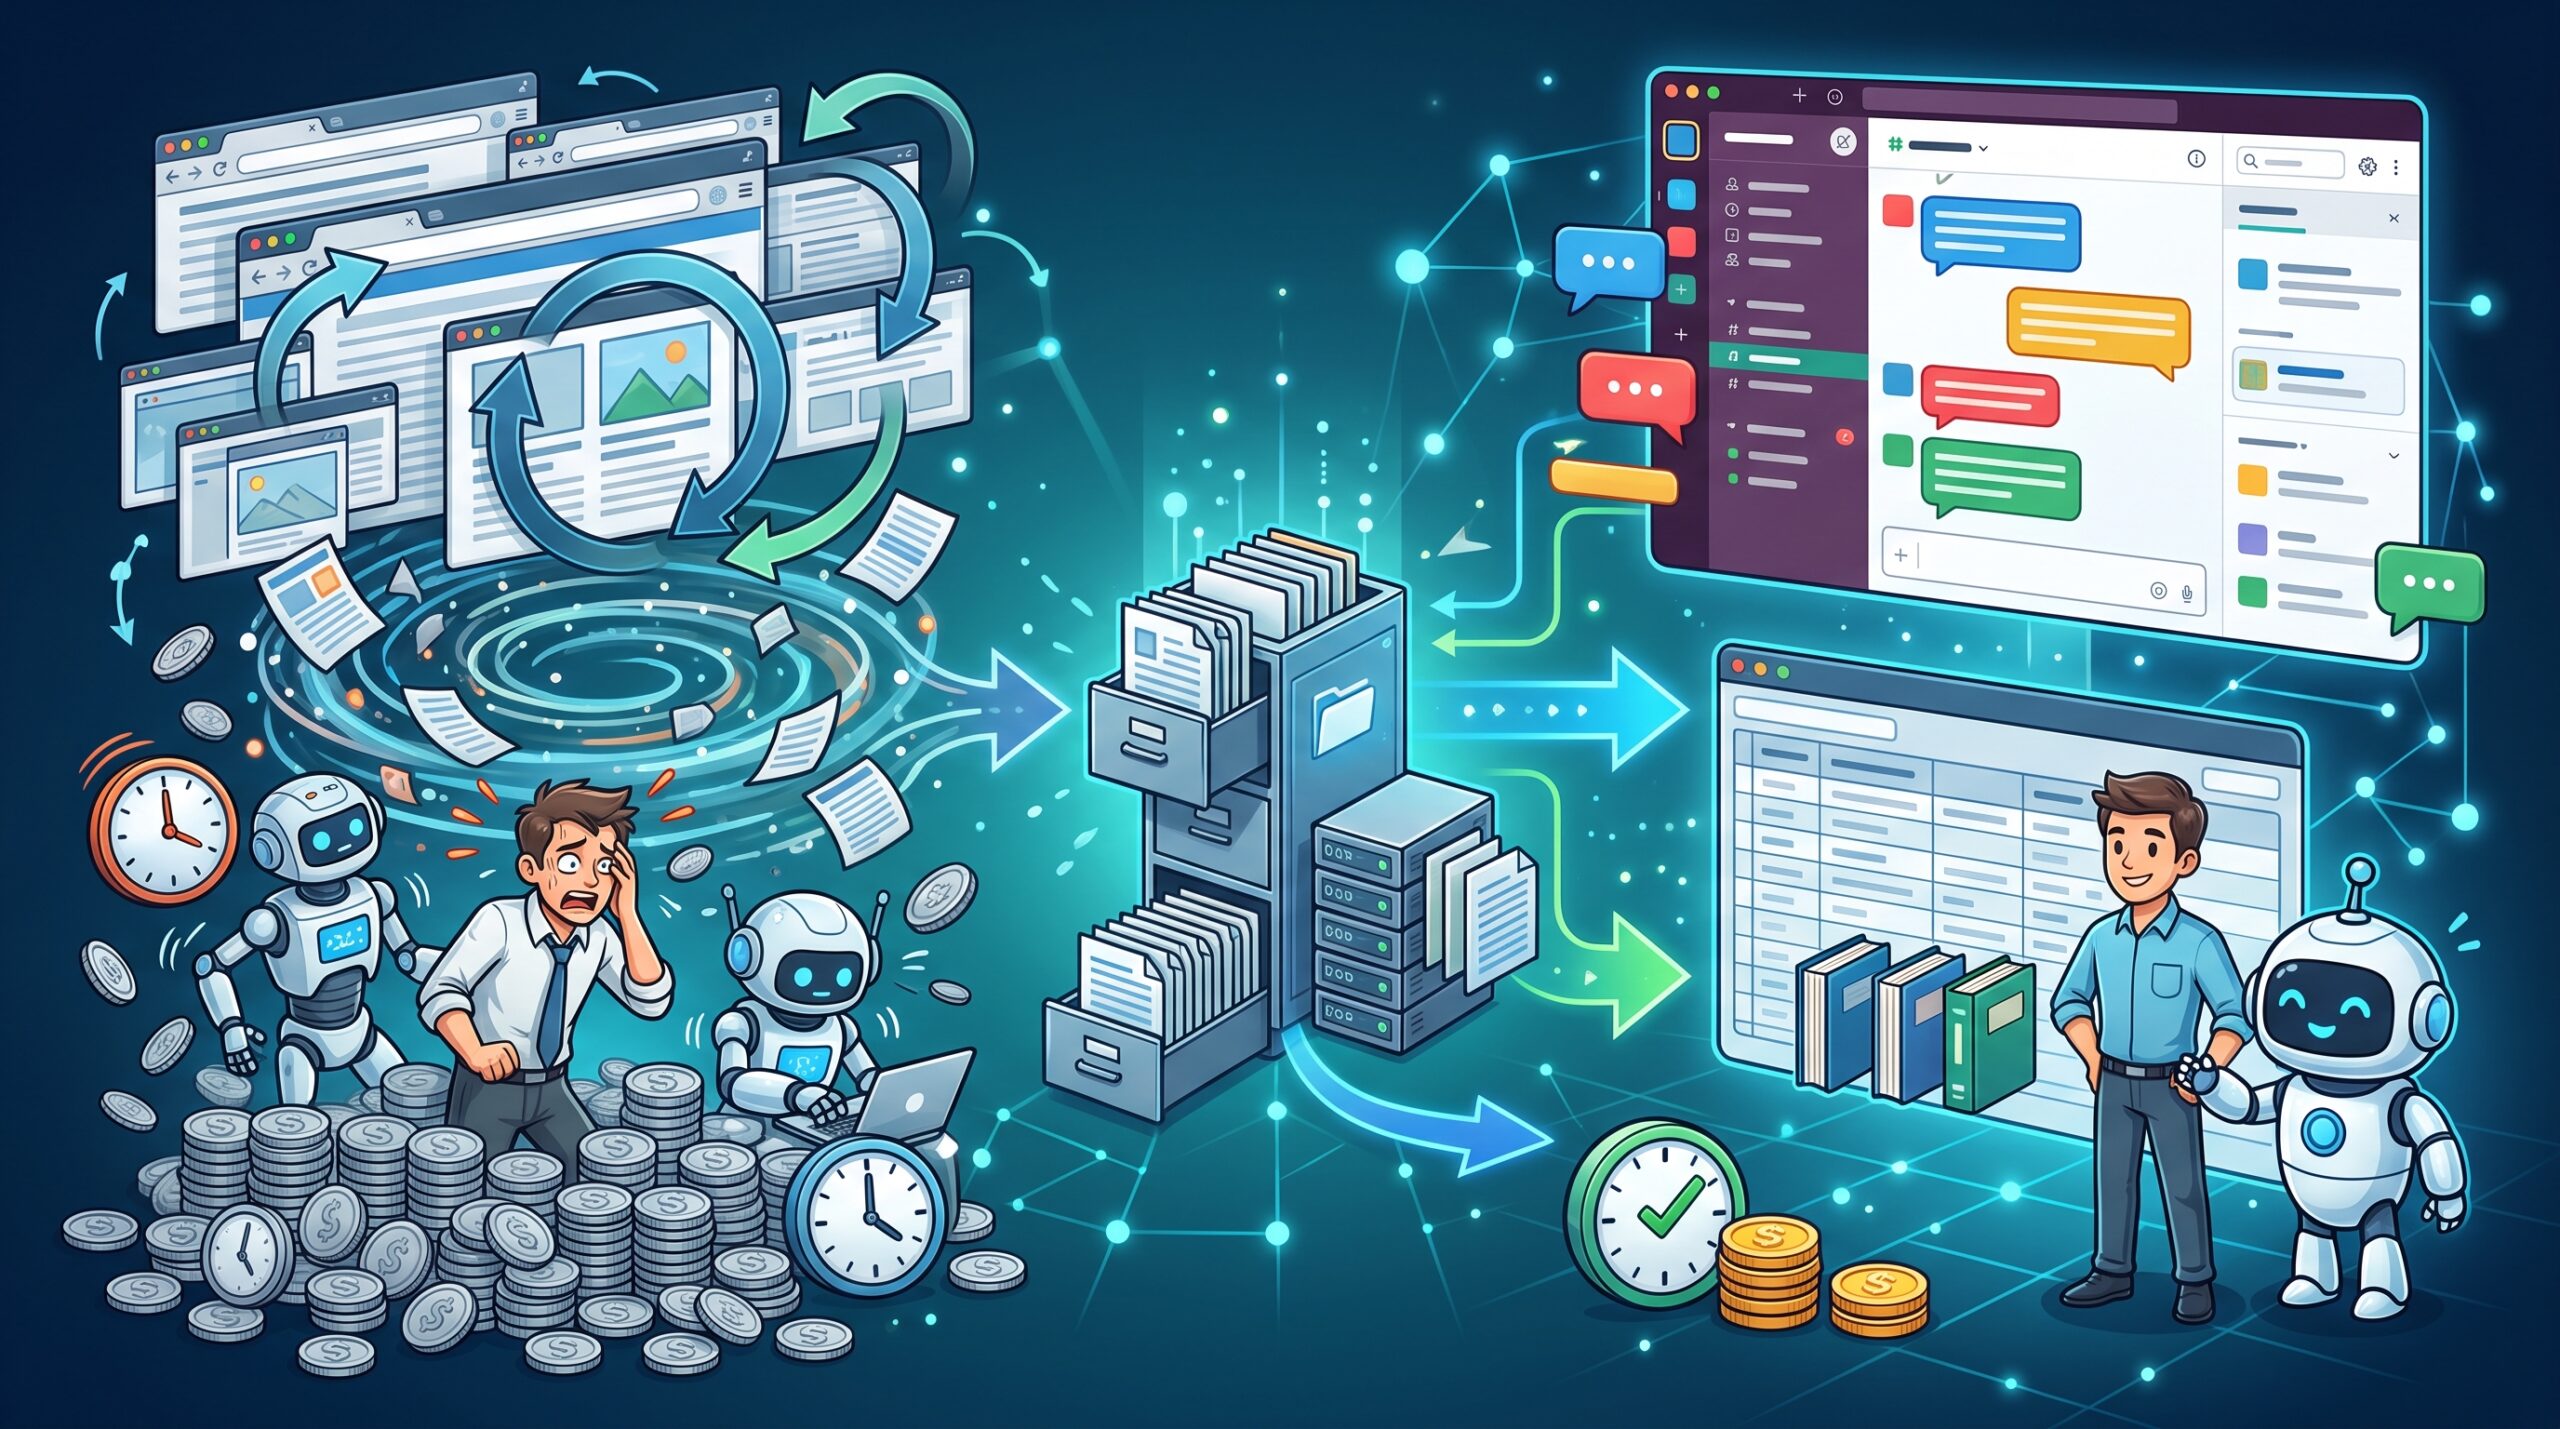
Asana announced that in tests optimizing StackAI’s browser-operating AI, a setup using GPT‑6.1 Sol achieved an estimated average model cost of $0.47 per run and an execution time of about four minutes. Compared with the original production setup, costs fell to about one-76th and processing became roughly five times faster.
The 76-fold reduction wasn’t achieved simply by switching models
Open a webpage, find the necessary information, and fill out a form. Unlike an AI that generates an answer once, a browser agent that handles these tasks calls a model repeatedly while working. At StackAI, which Asana acquired, customers can build automation workflows spanning multiple business apps without writing code.
The key point in these figures is that the roughly 76-fold reduction reflects both improvements to the workflow and a model change. Even with the original Model B, optimization cut the estimated model cost per run from more than $36.21 to $1.24. Using GPT‑6.1 Sol brought it down further to $0.47. A large part of the savings was achieved before switching models.
The costs cited here are estimates of model usage fees. They do not mean that total costs, including server expenses and development and operating labor, fell by the same proportion.
Cutting history too aggressively makes AI reread the same pages
Frank Hidalgo, StackAI’s CTO, who led the investigation, asked Codex’s GPT‑6 Astra to analyze the code and test possible improvements. One issue it found was that page content and screenshots were resent with every model request. Fixed instructions and other content could be reused, but the same mechanism was not being applied to the growing browsing history.
In addition, old images were deleted and text was truncated at nearly every step. Frequently rewriting the history makes it harder for the cache—which reuses previously processed inputs to reduce fees—to work effectively. Removing too much information can also lead the AI to revisit pages it has already read. Measures intended to shorten inputs could therefore end up increasing the workload.
Instead of deleting images each time, clean them up after collecting 20
The tests set history limits of 120,000 and 480,000 characters, varied the caching and image-management policies, and ran a total of 144 trials across four models. The task was the same in every case: gather six pieces of information for each of 32 books from a public demo catalog.
The optimized GPT‑6.1 Sol setup kept up to 20 screenshots and then retained only the newest one. Batching the cleanup instead of deleting images each time extended the period in which history could be reused without changes.
Even when comparing GPT‑6.1 Sol alone, revising caching and image management with a larger history limit reduced the estimated model cost from $1.97 to $0.47. After optimization, 89% of inputs went through the cache, and those inputs cost 5% of the price of standard inputs. The effective approach was not simply to reduce information, but to make the information retained easier to reuse.
Completion rates changed, not just costs
History management also affected whether tasks could be completed. With GPT‑6.1 Sol, an answer was generated in only three of 18 runs under the smaller history limit. With the larger limit, answers were generated in all 18 runs, and all were reported to be correct.
However, the comparisons of roughly 76-fold lower costs and fivefold faster execution need context. In the original setup, some runs hit the step limit before completion, so the figures of more than $36.21 in cost and more than 22.5 minutes represent lower bounds. The main comparison figures are also averages of three runs per setup and come from this specific information-gathering task. They do not establish that the same savings would apply to other websites or workflows.
Different models also have different strengths. After optimization, Model C cost $0.66 and took 3.5 minutes. It was more expensive than GPT‑6.1 Sol, at $0.47 and about four minutes, but ran faster. When evaluating deployment options, cost and speed need to be compared separately.
AI runs the experiments while people review the changes
In this case, GPT‑6 Astra not only proposed improvements but also made code changes and ran tests to ensure consistent experimental conditions. A separate model session reviewed the work, and requests and results were logged in Asana’s development platform, Command. Hidalgo said an investigation he estimates would have taken one to two months of manual work was completed in about a week. That timeline difference is his estimate, not the result of a comparative experiment involving human work.
The takeaway from this case is that when assessing AI operating costs, there may be as much room to investigate how models are called and how history is managed as there is to look at model pricing. Asana has applied the changes to StackAI’s browser-operating feature. The company plans to build tests into its evaluation feature so customers and internal teams can compare costs, execution times, and answer quality across different configurations.

Comments