
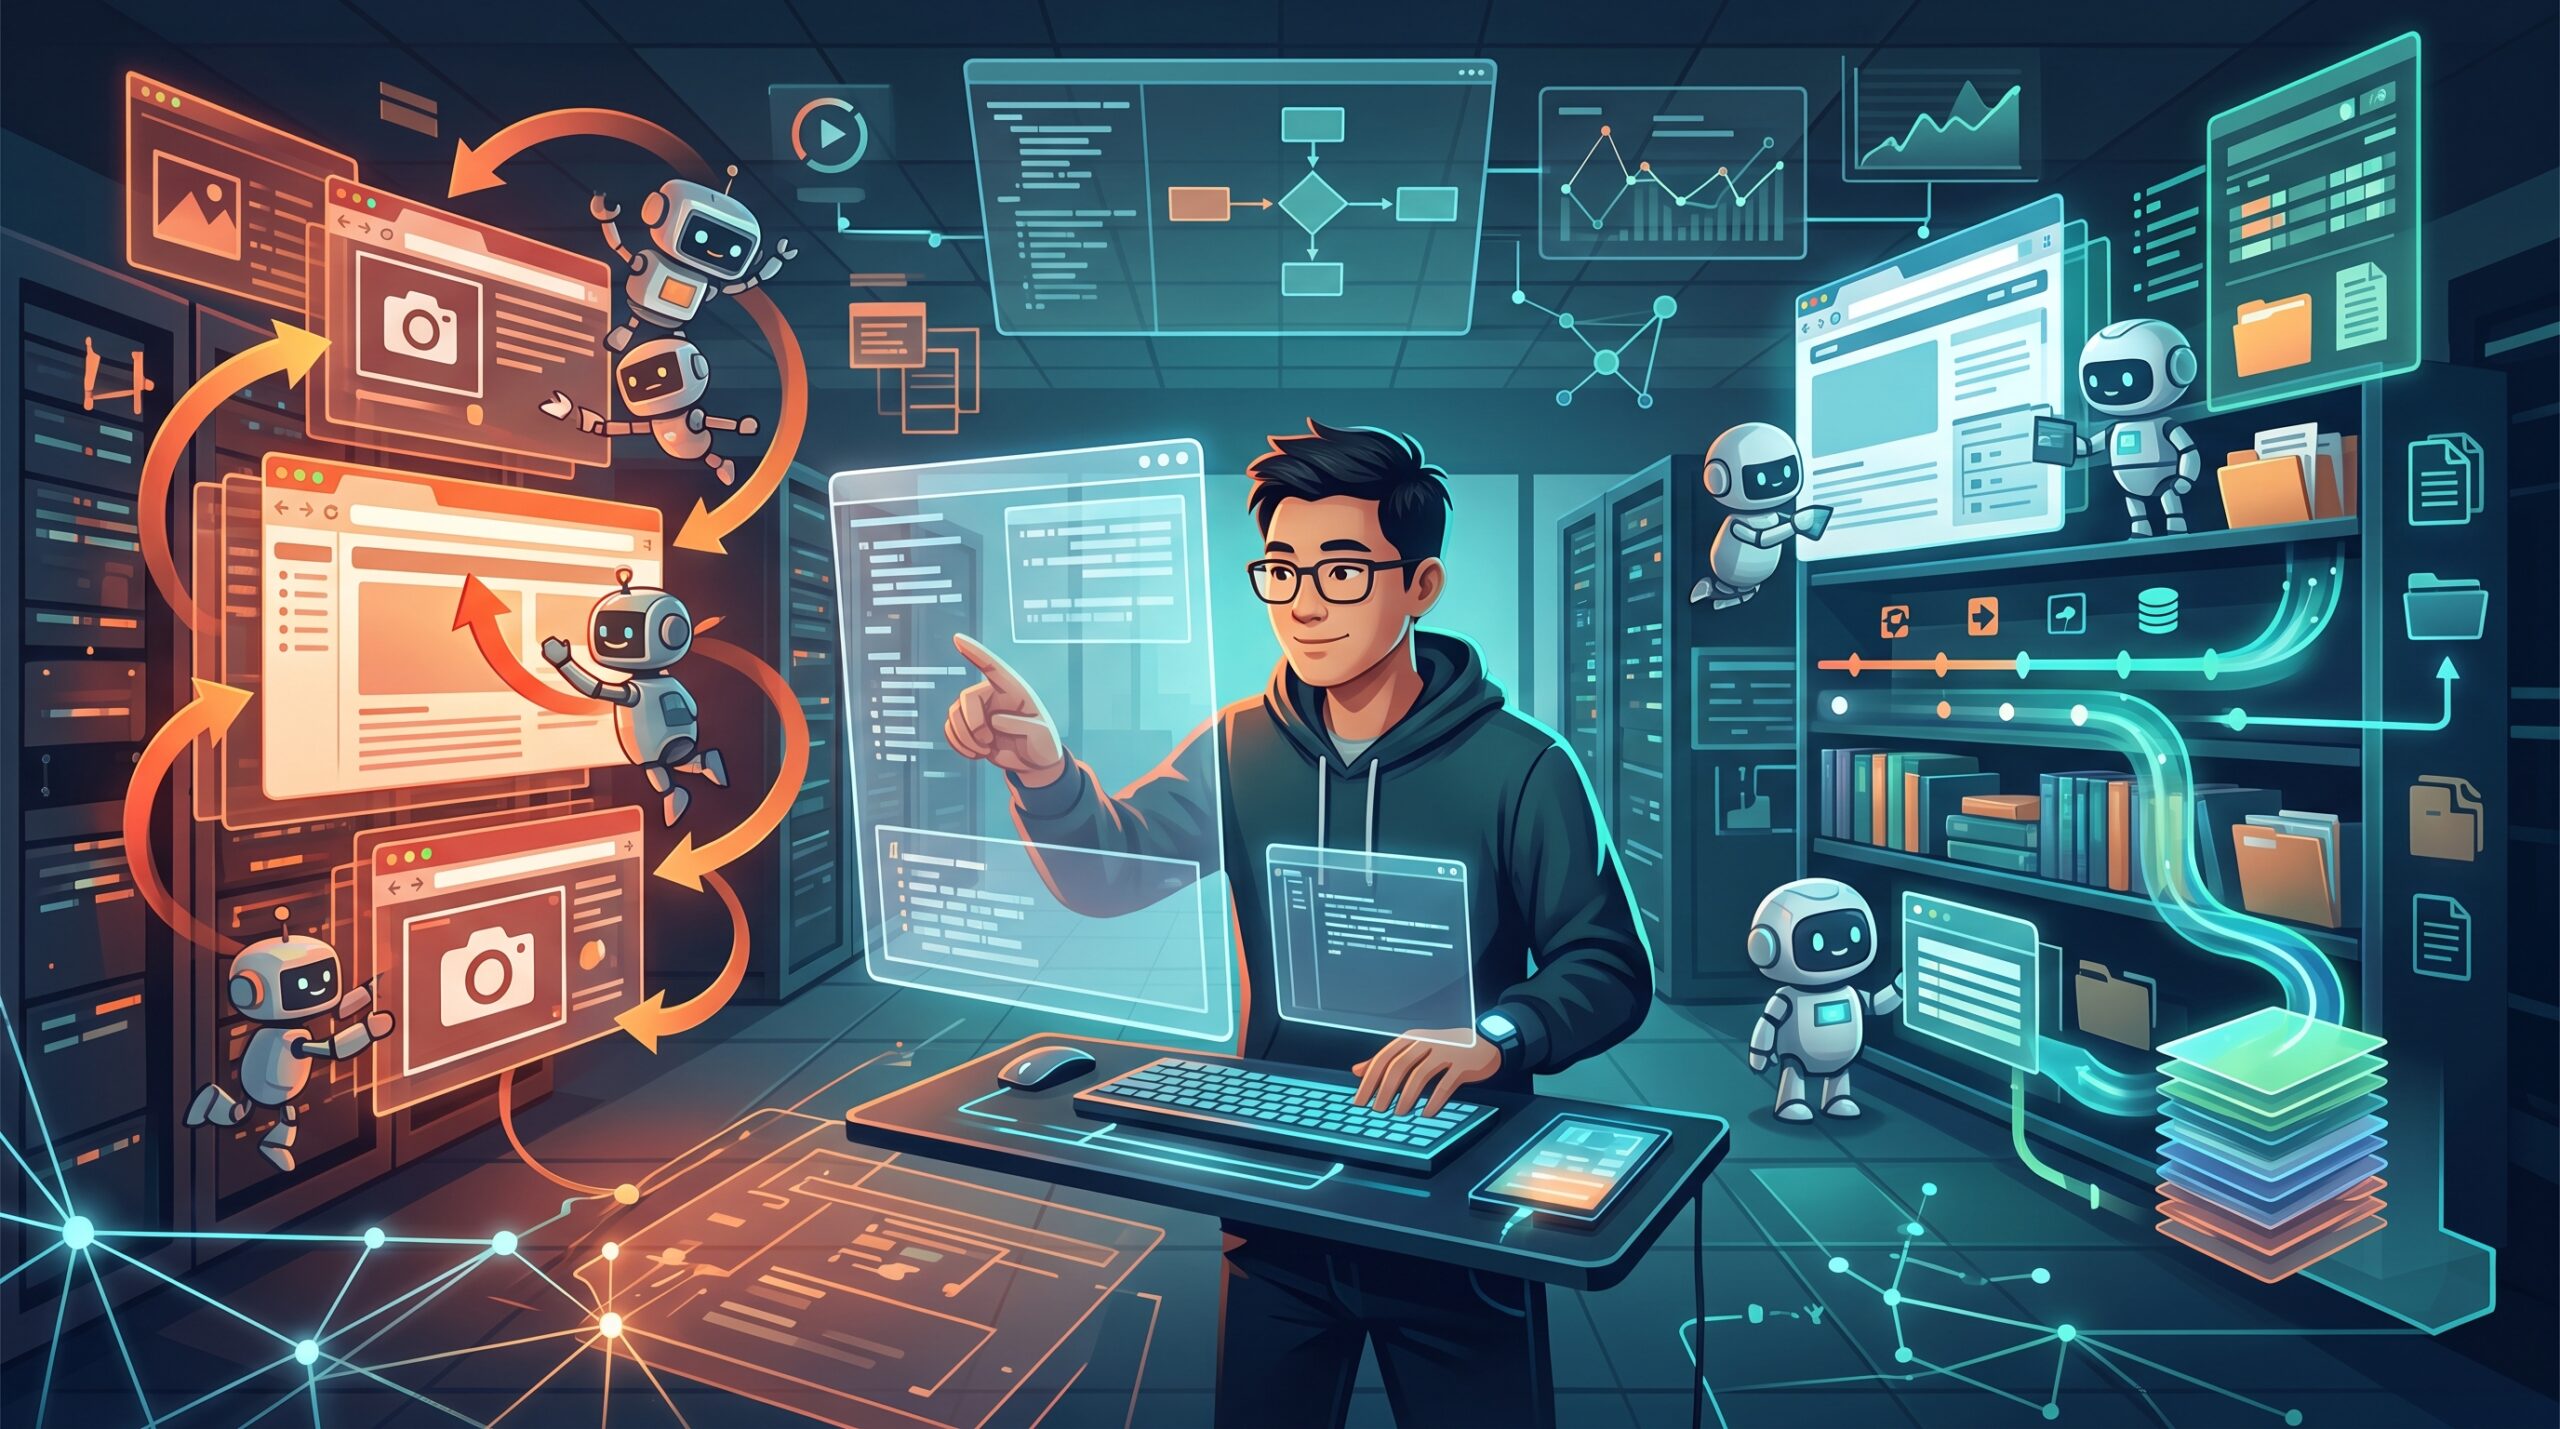
Asana announced that, in tests of StackAI’s AI for automating browser interactions, it cut estimated model costs to one-76th of those in its previous production setup while making processing five times faster. With GPT‑6.1 Sol and an optimized approach to managing browsing history, each run took about four minutes on average and cost $0.47.
The 76-fold reduction wasn’t achieved just by switching models
The key point about these figures is that they compare not the performance of models alone, but the results of combining a model with a processing setup. A browser agent is an AI that reads web pages and carries out tasks such as gathering information and filling in forms. Through its acquisition of StackAI, Asana offers automation for this kind of work.
In the test, the system gathered six pieces of information for each of 32 books from a public demo catalog. It ran 144 tests across four models and multiple configurations. With the Model B used initially, the estimated model cost per run was at least $36.21, but simply revising the processing setup brought it down to $1.24. An optimized configuration using GPT‑6.1 Sol reduced it further to $0.47.
In other words, costs fell by about 29 times even while using Model B. Behind the headline figure of a 76-fold reduction, improvements to the processing design before choosing a model played a major role.
The key to savings was the browsing history given to the AI
In the previous setup, fixed instructions and similar inputs were cached, but accumulated page text and screenshot history were not. Caching is a way to reuse inputs that have already been processed. If history cannot be reused, past information must be sent again every time the AI is called, incurring additional charges.
What’s more, old images were deleted and text shortened at nearly every step. Because the history was rewritten frequently, simply introducing caching was unlikely to be effective. Removing too much information can also cause the agent to revisit pages it has already read.
The team therefore increased the history retention limit from 120,000 to 480,000 characters and made browsing history eligible for caching. It also adopted a system that stores up to 20 screenshots before keeping only the latest one. By organizing the history in batches rather than on every run, the team extended the period during which past history could be reused without changes.
Keeping more information can also lower costs
The assumption that giving AI less information makes it cheaper cannot, by itself, explain agent costs, these results suggest. Retaining and reusing information, and reducing unnecessary rechecks, can make the overall process less expensive.
For GPT‑6.1 Sol, revising caching and image management while increasing the history retention limit brought the estimated model cost per run down from $1.97 to $0.47. After optimization, 89% of input came from the cache, and the cost for that portion was 5% of what it would have been without caching.
The amount of history also affected task completion. GPT‑6.1 Sol generated an answer in just three of 18 runs when the retention limit was low, but in all 18 runs when it was higher. All 18 answers in the test were correct.
AI was also used to test proposed improvements
Separate from GPT‑6.1 Sol, which performed the browser interactions, GPT‑6 Astra in Codex was used for research and improvement work. It examined the code structure, identified problems with history management, reworked the code for experiments, and tested multiple configurations in parallel.
That does not mean humans were absent from the process. Frank Hidalgo, StackAI’s CTO, reviewed the proposals and selected changes to test. Experiment records and outputs were also reviewed in separate model sessions and retained in Asana’s development platform, Command. Changes went through tickets and pull requests before being deployed to production.
Hidalgo said that research he estimates would have taken one to two months by hand was completed in about a week. This time comparison is based on his estimate; it is not the result of a controlled experiment in which humans performed the same work alone.
Evaluate costs and completion rates together when deciding whether to adopt
The $0.47 figure is an estimated model cost, not a total cost that includes labor or system operating expenses. In addition, some of the baseline configurations did not complete because they hit the limit on the number of processing steps, so the figures of at least $36.21 and at least 22.5 minutes are lower bounds. The main comparison figures are averages of three runs per configuration, and the same rate of savings cannot be assumed for every web task.
Among the optimized configurations, Model C cost $0.66 and took 3.5 minutes, while GPT‑6.1 Sol cost $0.47 and took about four minutes. Sol was cheaper for this task, but Model C was faster, so the rankings differed for cost and speed.
Asana has applied these changes to StackAI’s browser-interaction feature. Going forward, it plans to incorporate testing into the platform’s evaluation capabilities, allowing customers and internal teams to compare cost, execution time, and answer quality across configurations.

Comments